Text Generation
1. What is Text Generation?
Text generation is one of the key tasks in large-scale model inference services. Its goal is to automatically generate coherent text based on a given input prompt. This task is widely used in various fields such as intelligent writing, dialogue systems, code generation, summarization, and more.
2. Typical Use Cases
- Content Creation: Generate articles, stories, poems, advertising copy, etc.
- Dialogue Systems: Provide natural and fluent conversational abilities for intelligent assistants and chatbots.
- Code Generation: Automatically generate code based on requirements, improving development efficiency.
- Text Summarization: Summarize lengthy documents to extract key information.
- Machine Translation: Automatically translate text from one language to another.
3. Key Factors Influencing Inference Quality
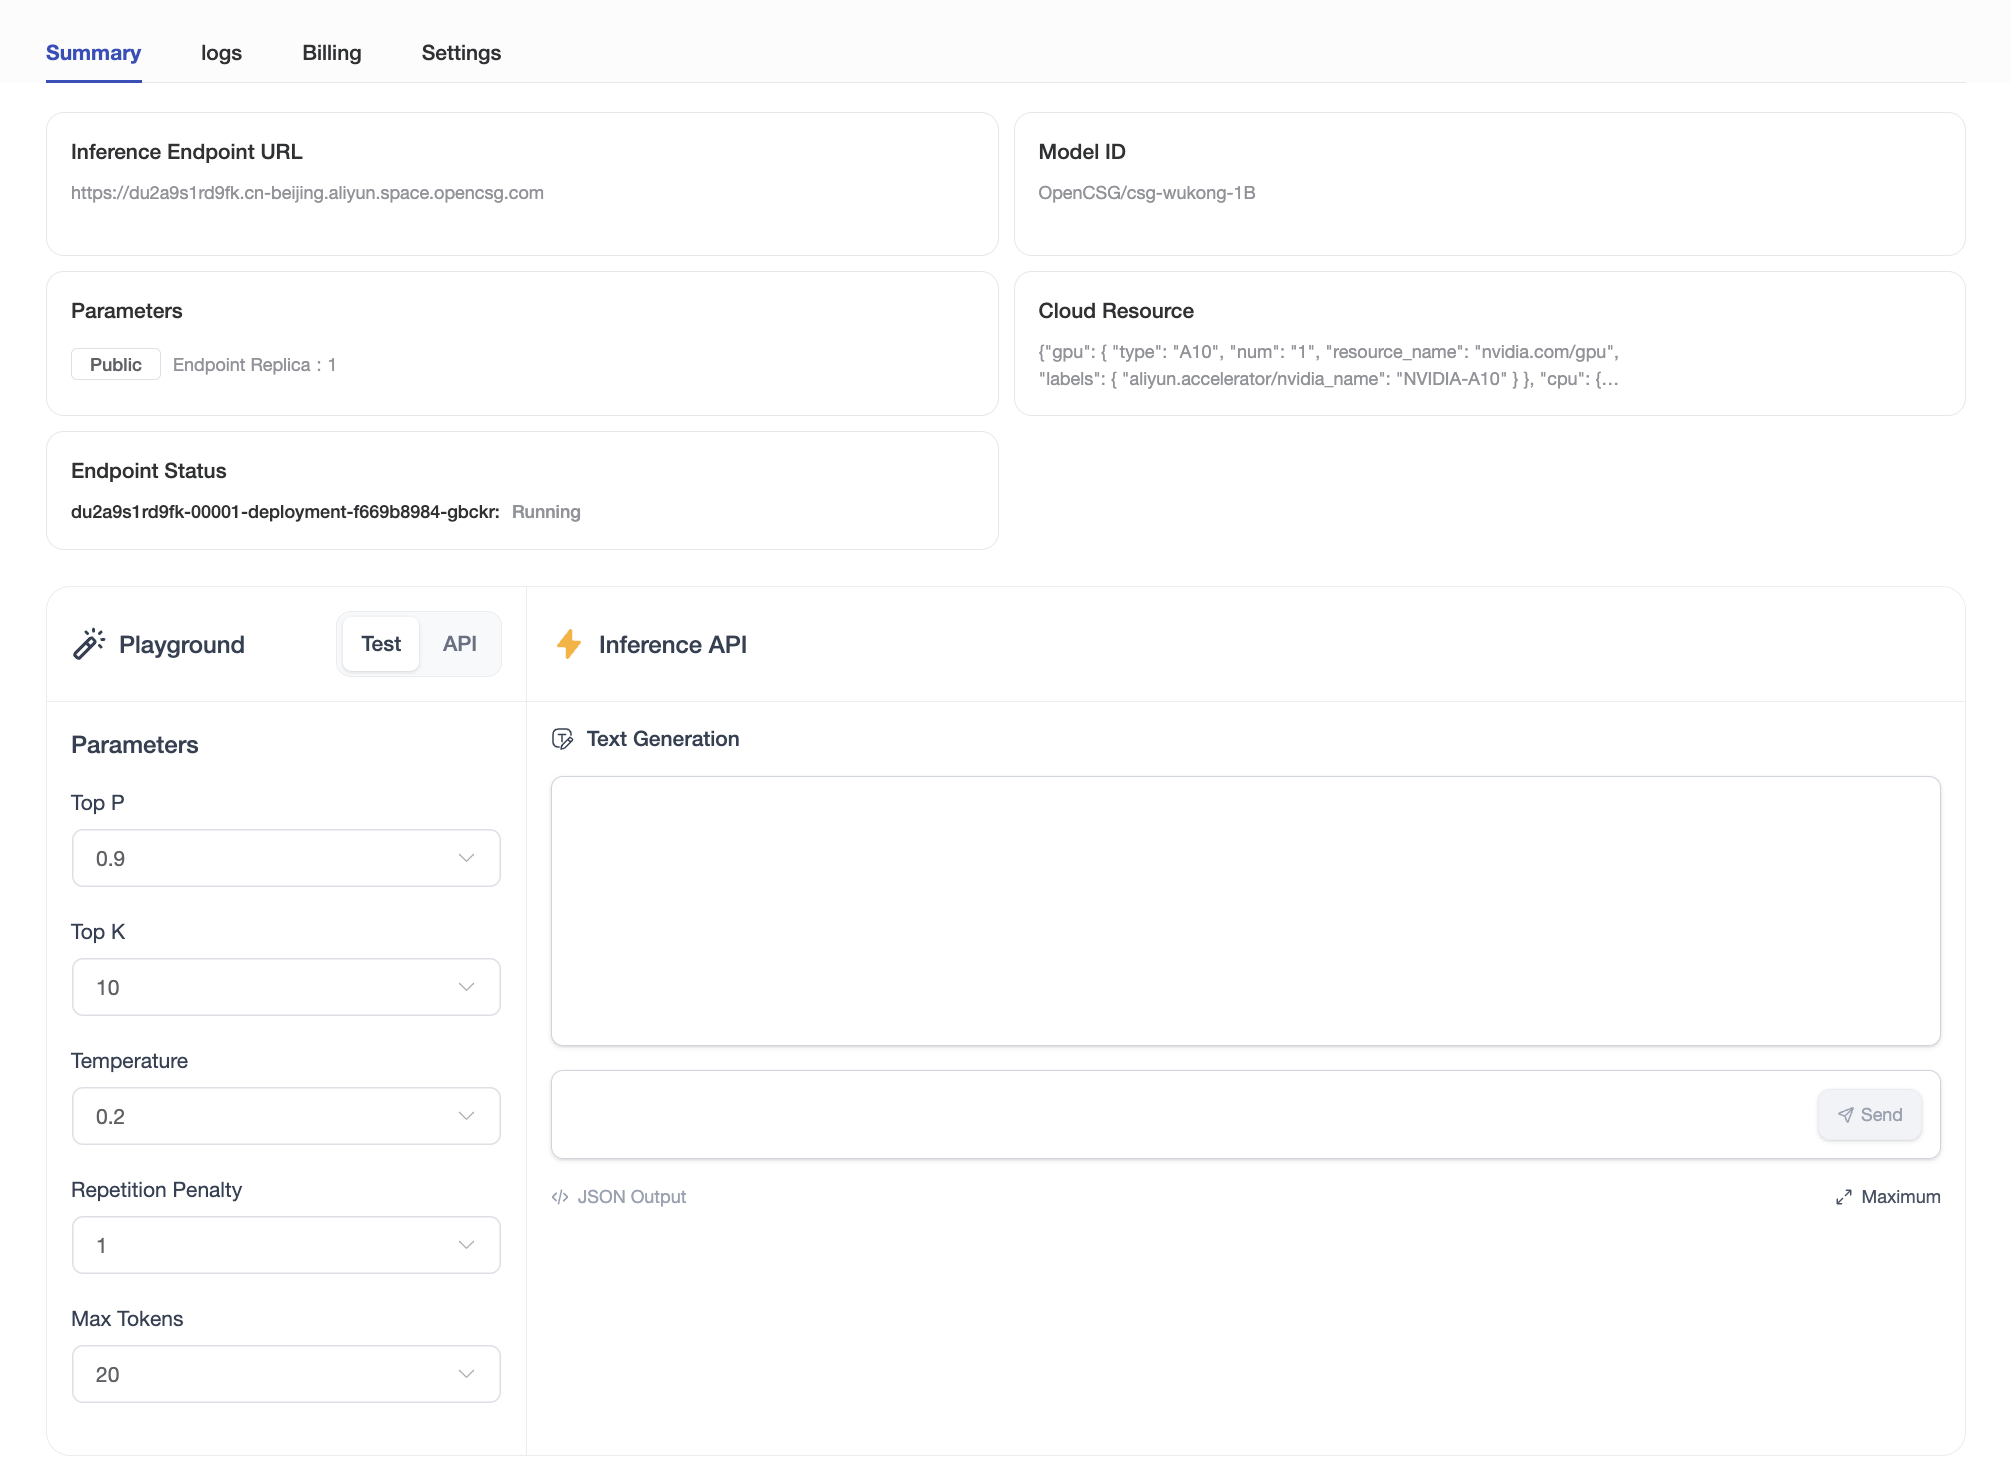
Model Selection
Different models exhibit various strengths in text fluency, accuracy, and other aspects. Choosing the right model for specific tasks is crucial.
Parameter Tuning
The following parameters play an important role in determining the quality of text generation:
Temperature
- Controls the creativity of the generated text.
- High temperature (e.g.,
1.0): Outputs are more diverse and creative, but might lack precision. - Low temperature (e.g.,
0.1): Text is more stable and predictable but may feel monotonous.
- High temperature (e.g.,
- Use Cases: Suitable for controlling the degree of text freedom.
Maximum Length
- Sets the limit on the number of words generated to prevent overly lengthy or short results.
Top-K Sampling
-
Limits the model to consider only the
Kmost probable words when generating text. -
For example,
K=50means the model selects from the 50 most relevant words, improving quality and reducing randomness. -
Use Cases:
-
Use smaller
top_kvalues when generating formal or precise text. -
Use larger
top_kvalues for more creative and diverse outputs. -
Setting
top_kto0(or leaving it unset) disables top-k sampling.
Top-P Sampling
-
Dynamically selects words based on probabilities rather than a fixed quantity.
-
For instance, it considers words cumulatively until their combined probability reaches
90%, offering more flexibility. -
Use Cases:
-
Use
top_pto find a balance between randomness and diversity in generated results. -
Setting
top_pto1(or leaving it unset) disables top-p sampling.
Repetition Penalty
- Controlling for the model's preference for repetitive phrases, higher penalties can reduce redundant content.
- Use Cases : Avoid repeating the same words or sentences when generating content.
4. Sample Code
import requests
url = "https://xxxxxxxxxxxx.space.opencsg.com/v1/chat/completions" #endpoint url
headers = {
    'Content-Type': 'application/json'
}
data = {
    "model": "xzgan001/Qwen2-1.5B-Instruct-GGUF",
    "messages": [
        {
            "role": "system",
            "content": "You are a helpful assistant."
        },
        {
            "role": "user",
            "content": "What is deep learning?"
        }
    ],
    "stream": True,
    "temperature": 0.2,
    "max_tokens": 200,
    "top_k": 10,
    "top_p": 0.9,
    "repetition_penalty": 1
}
response = requests.post(url=url, json=data, headers=headers, stream=True)