Downloading Datasets
If you want to get and download the datasets on CSGHub, we currently support downloading datasets via Git, web interface, command line and SDK. Below are the detailed steps for each method:
Downloading Datasets Using Git
Copy the clone URL from the current repository. Replace the sample host, namespace and repository; use the SSH port configured for your deployment.
Use HTTPS. For private repositories, authenticate with the deployment's account and Access Token:
git lfs install
git clone https://opencsg.com/datasets/your-namespace/example-dataset.git
Use SSH after adding your public key under Account settings → SSH Keys on the same deployment:
git lfs install
git clone ssh://git@hub.opencsg.com/datasets/your-namespace/example-dataset.git
Inspect downloaded content. If only Git LFS pointers are present, run git lfs pull inside the local repository and check permissions, network and disk space if it fails.
Downloading Files Using Web Interface
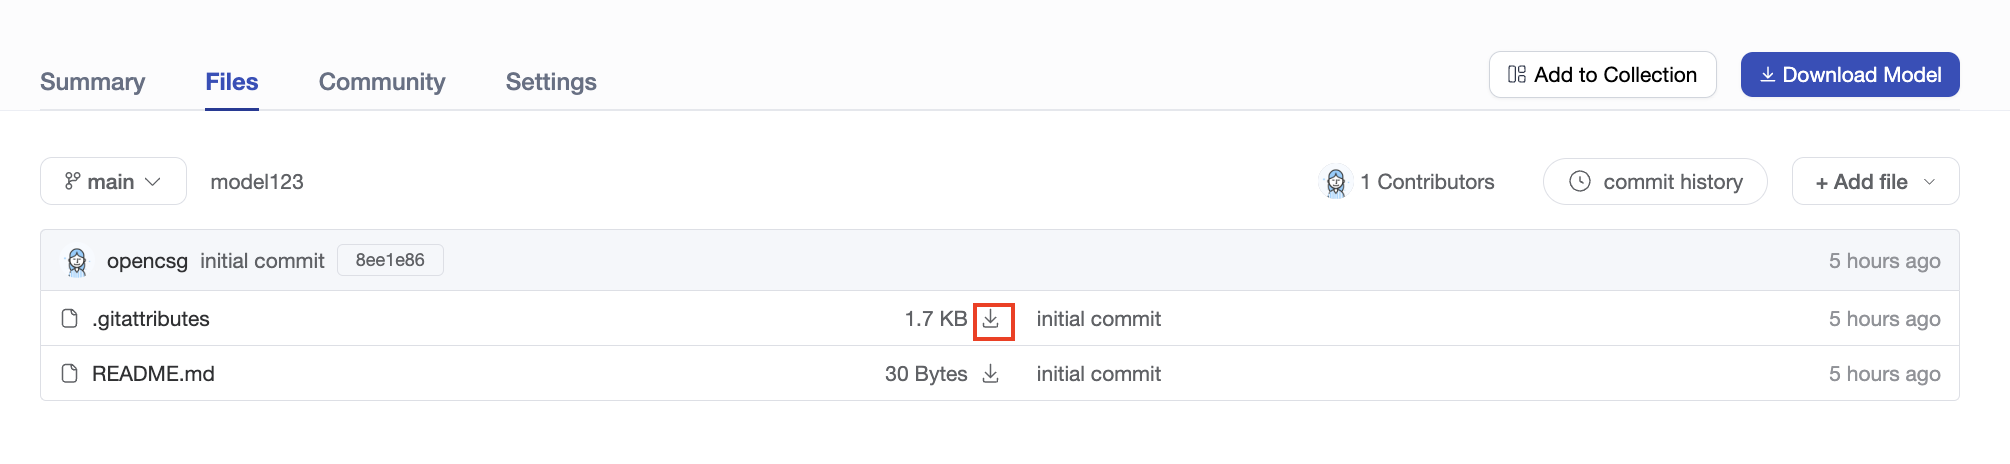
In the repository's Files tab, locate the target file and select its download button. Check the downloaded name and content. To retrieve the entire repository, use the Git workflow on this page.
Download with the CLI
Install a compatible csghub-sdk and inspect csghub-cli download --help. Set this site's CSGHUB_TOKEN in the runtime and use its platform API endpoint, not the inference gateway. Replace the repository ID with one you can access.
export CSGHUB_ENDPOINT="https://hub.opencsg.com"
csghub-cli download your-namespace/example-dataset \
  --repo-type dataset --endpoint "$CSGHUB_ENDPOINT"
Download with the SDK
Reuse CSGHUB_ENDPOINT and CSGHUB_TOKEN:
import os
from pycsghub.snapshot_download import snapshot_download

result = snapshot_download(
    "your-namespace/example-dataset",
    repo_type="dataset",
    endpoint=os.environ["CSGHUB_ENDPOINT"],
    token=os.environ["CSGHUB_TOKEN"],
    cache_dir="./csghub-cache",
)
print(result)
Verify downloaded files and the repository version. If only LFS pointers are present, retrieve the actual large files. Check the address, repository type, ID and permissions when a request fails.